
inference engineering 101 - what it really takes to serve an AI model at scale
inference engineering 101 - what it really takes to serve an AI model at scale
Hosted by
About the event
Anyone can call an LLM API.
Making models fast, affordable and reliable when millions of requests hit them is a different skill entirely.
That's inference engineering, and it's quickly becoming one of the most valuable skills in AI.
This meetup is a practical deep dive into the field, built around Philip Kiely's Inference Engineering (Baseten), the first real textbook on the subject, and grounded in real production experience.
Your host:
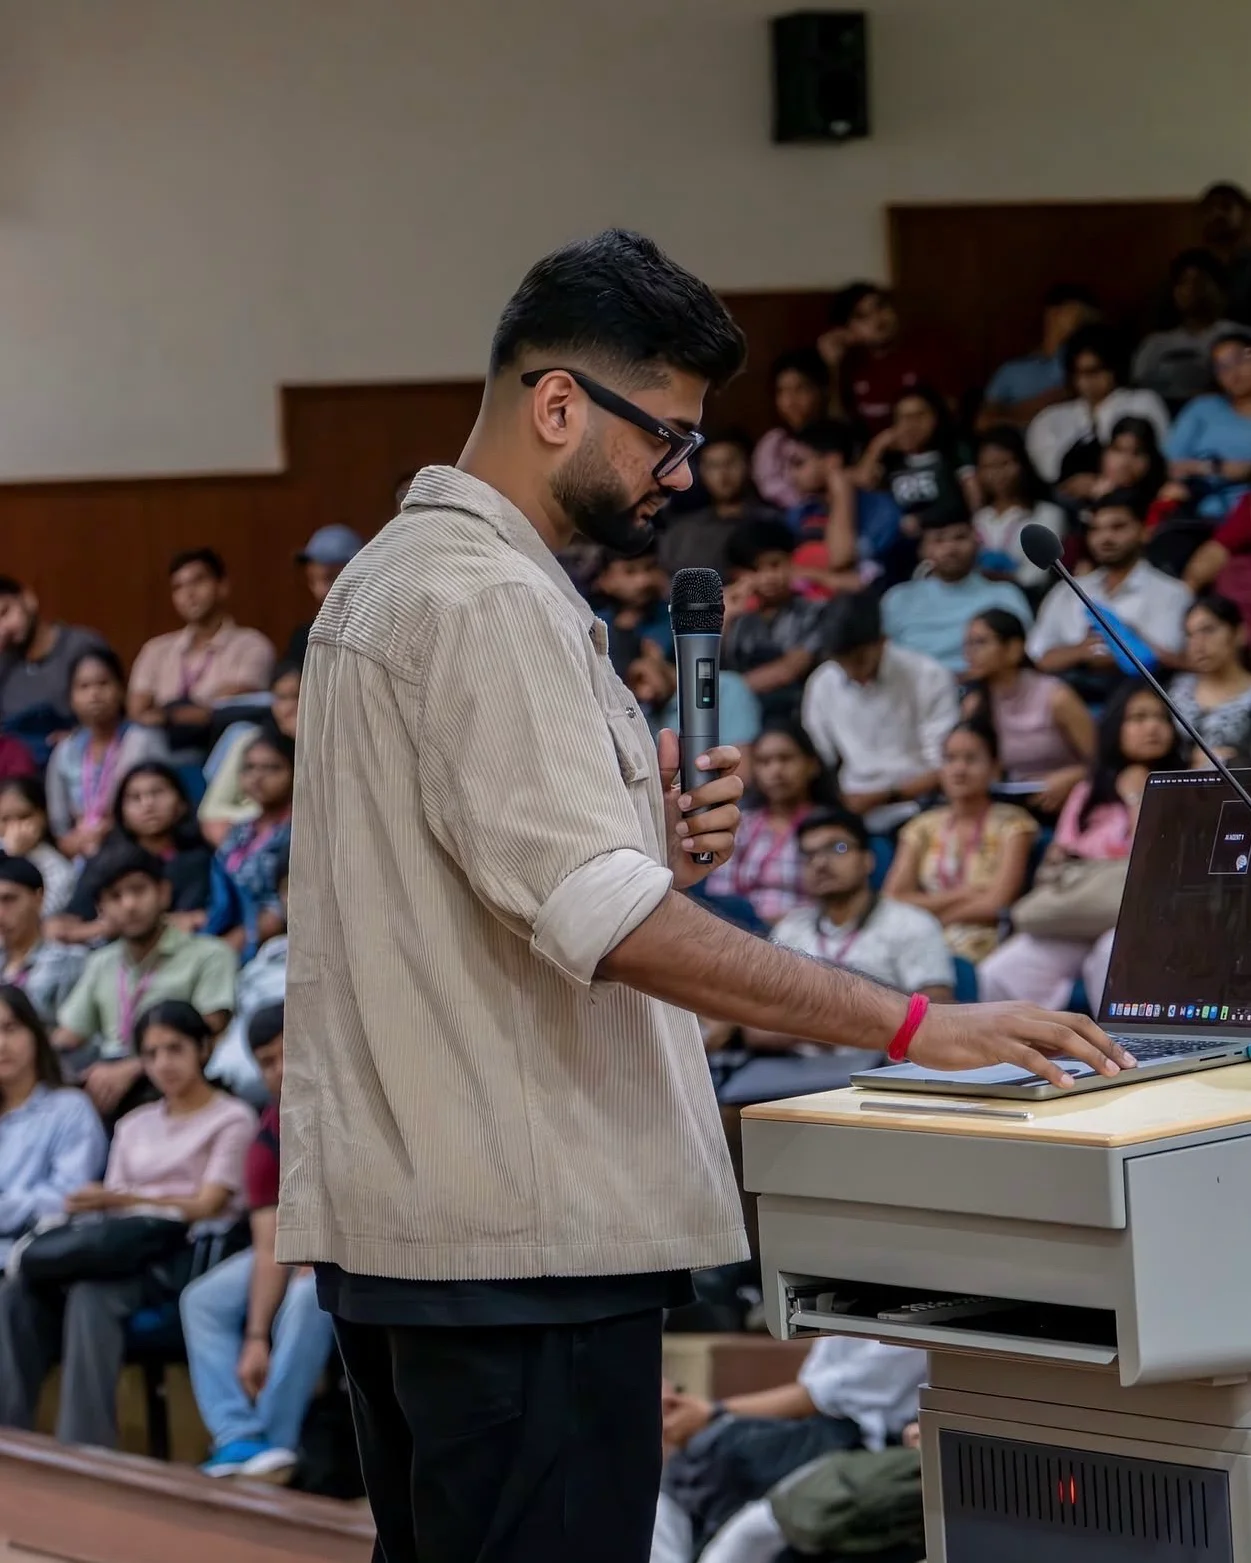
Ishan Dutta, Machine Learning Engineer III at Adobe (ex-NVIDIA). For the past year at Adobe, I have been running inference at the scale of millions of requests, powering large-scale data pipelines.
Expect lessons from the book alongside what actually holds up (and what breaks) in production.
What you'll walk away with:
- How LLMs actually generate text:
The prefill and decode phases, the KV cache, and why GPU memory, not raw compute, is usually the real bottleneck
- How to measure what matters:
Time-to-first-token, throughput and tail latency, and how batching trades one against another
- The optimization toolkit:
What quantization, caching and speculative decoding actually do, what each one costs you, and where engines like vLLM fit in
- Lessons from production:
Running inference inside high-volume data pipelines, and deciding when to use a hosted API versus serving your own model
Who should come -
Software, backend, ML and data engineers, AI builders, founders, and technical product folks.
If you've built something with an LLM API and want to understand what happens underneath, host open source models on your compute, this is for you.
This is a beginner friendly workshop. Python comfort helps. No GPU or CUDA experience needed.
Format -
Limited seats - 2 hours: a focused intuitive walkthrough of each concept followed by technical details, then open discussion where attendees share their own setups and war stories.
Deliberately small, so the conversation goes deep.
Location -
To be decided
Location
Bengaluru